Three reviewers, three answers: Claude. Claude outperformed the other two major AI writing models in the most human-sounding writing in a blind test that included 134 people and eight writing types: blog posts, emails, essays, product descriptions, technical documentation, stories, social posts, and cover letters. The most versatile and most easily detected is ChatGPT. In the middle, as it were, is Gemini, which is consistent but formulaic.
However, this answer is preceded by a disclaimer that is typically omitted from the headline, and that is none of them write text that is consistently AI-undetectable without further tweaking. But not only is the question at stake which model sounds most human, but the question is why, how much, and what can be done about the gap that still exists.
The Blind Test Results
The HumanizeThis AI comparison is the purest head-to-head comparison that’s available: 134 participants and eight tasks, blind judging. Claude won 4 out of 8 and was the model that was most often identified as “could be human. That testing saw it detected at 23%, compared to 68% for ChatGPT and 61% for Gemini.
A second independent study, from TextSight (which tested 50 samples across three different types of content and three detectors), found the same result, but in absolute terms: ChatGPT was 91%, Gemini was 84%, and Claude was 78%, with Claude the lowest and the reasons structural, not superficial. There is a difference of 13 percentage points between the “best” (Claude at 78%) and the “worst” (ChatGPT at 91%), a difference that is, indeed, significant, but one that also reveals that Claude, the most difficult to detect model, is still detected 78% of the time on raw, unedited output.
A third benchmark places the range at ChatGPT 92–96%, Claude 75–85%, and Gemini 70–82%, depending on the type of prompt and version. The numbers change from study to study since detectors are different and constantly updated, but the ranking doesn’t change. In all tests, Claude did better than both Gemini and ChatGPT.
Why Claude Sounds Human
The reasons are structural. Claude’s sentences vary in length more than ChatGPT’s. It can make more claims, generating text that sounds more like a professional human writer, leading to marginally higher perplexity, the most important AI detector metric. It is slightly more variable in length than the sentences in ChatGPT, but less than that of humans.
In simple terms: Claude feels like a thoughtful human, ChatGPT feels like an efficient assistant, and Gemini feels like a well-researched report. It remembers details about the characters, keeps the tone even through longer runs of text, and writes the dialogue without the sound of everyone going to the same corporate communication workshop. Although ChatGPT has come a long way, it still tends to stick to bullet points and a very formal, verbose register. Technically correct, it has a tendency to be very verbose and to have a structure that is very linear and list-like, which is detected at 61% by document-level detection.
Here is another detector-training bias to know: detectors were trained with many of the ChatGPT outputs since ChatGPT currently has more market share; they therefore tend to be more tuned toward ChatGPT patterns than to Claude’s. One of Claude’s strengths is that he writes in ways that don’t match the ways the detectors were trained to recognize, which diminishes as detectors retrain.
The Honest Caveat: No Model Passes Raw
This is something most “best AI writer” posts miss out on. The flagging rate is 77-78% on raw output, even for Claude. When giving raw Claude text to any decent AI detector, you’ll send that about 4/5 times. The model’s decision shifts the chances; it is not a solution to the problem.
The detectors, in turn, are imperfect in the other direction: Stanford HAI research found that seven different detectors misclassified 61.22% of non-native English essays. Detection is a statistical guess and not a verdict; that is why the winning strategy was never “pick the least detectable model and publish raw”. Pick the best starting point and then make it yours.
The human layer is what makes AI text sound human: editing for your voice, adding specific experience and opinion, changing the rhythm on purpose, cutting out filler phrases and defaults to bullet points. Light editing drastically reduces detection rates across models, and genuine human revision makes little difference in detection rates between models but a great deal between different judgments.
The Multi-Model Answer
This is where the “which model” question dissolves into a better one: why choose one model at all? Each model wins on different tasks: Claude for natural prose and editing, ChatGPT for structured, ready-to-use output and speed, Gemini for research-heavy content with current web data. The smart workflow uses all three: Gemini for the research, Claude for the draft, ChatGPT for the structure check, and your own judgment for the final pass.
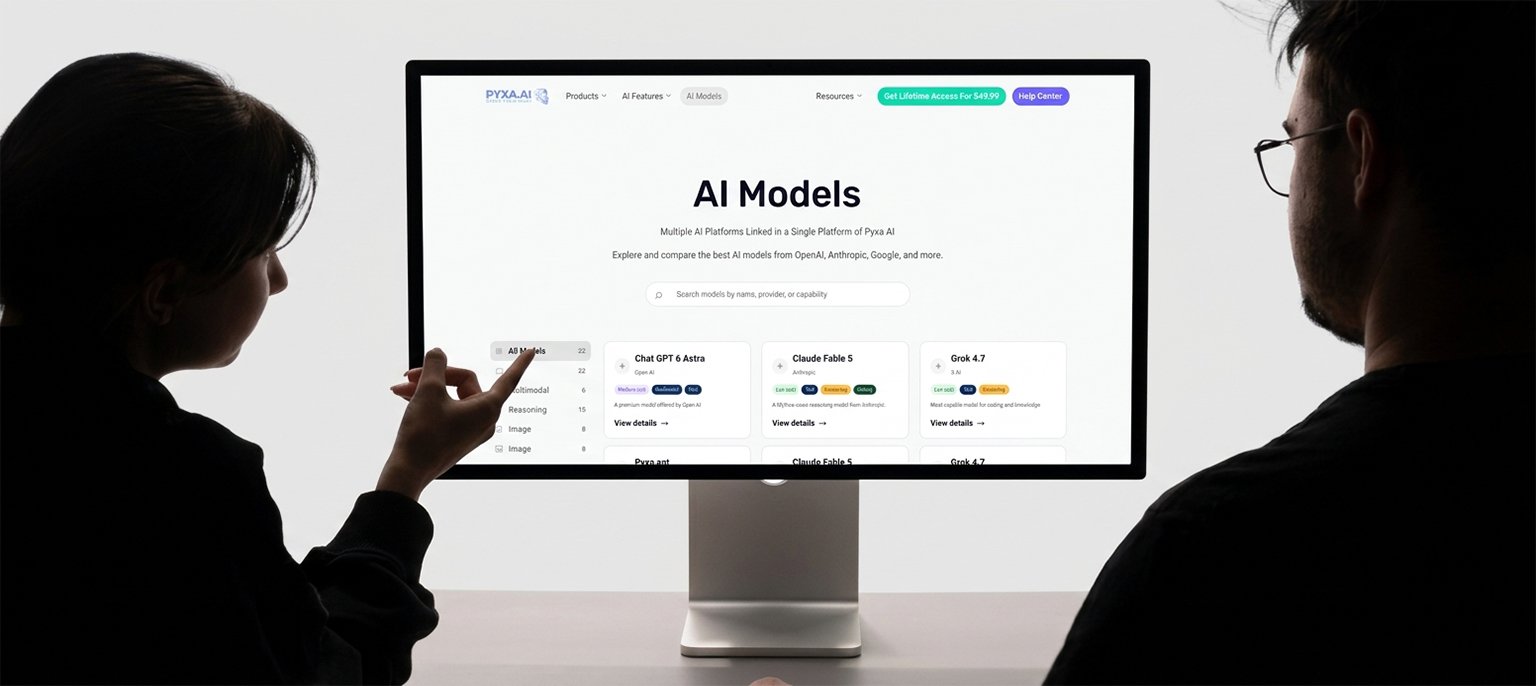
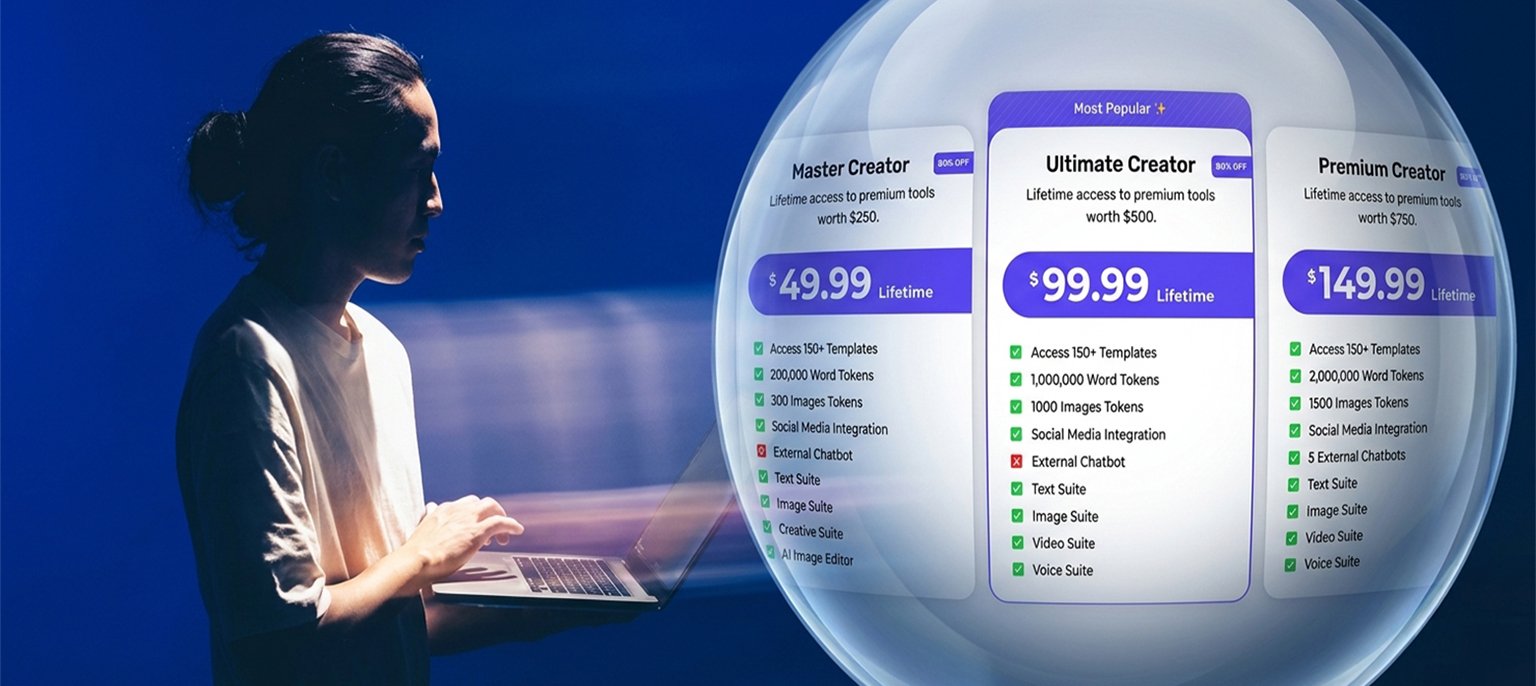
Pyxa AI’s Multi-Model AI is built for exactly that workflow: multiple AI models in one workspace, one login, one $49.99 lifetime payment, instead of three $20-a-month subscriptions ($59.99 a month) just to compare how each model writes. Draft with the model that sounds most human, fact-check with the one that knows the web best, structure with the fastest, then publish through the same platform’s SEO tools and WordPress integration, and narrate it with the Voice Studio. The model is a starting point. The workflow is what makes it human.
The Bottom Line
Claude writes the most human-sounding content right now; the blind tests, the detection rates, and the reviewers all agree. But the model is only the starting point. No AI writes publish-ready human prose raw, and the writers who sound most human in 2026 aren’t the ones who picked the right model. They’re the ones who use the best model for each job, then bring their own voice, experience, and judgment to the final draft.
Every model, one workspace, one lifetime payment, draft it human with Pyxa AI.